
Head to head
LaunchDarkly vs Statsig
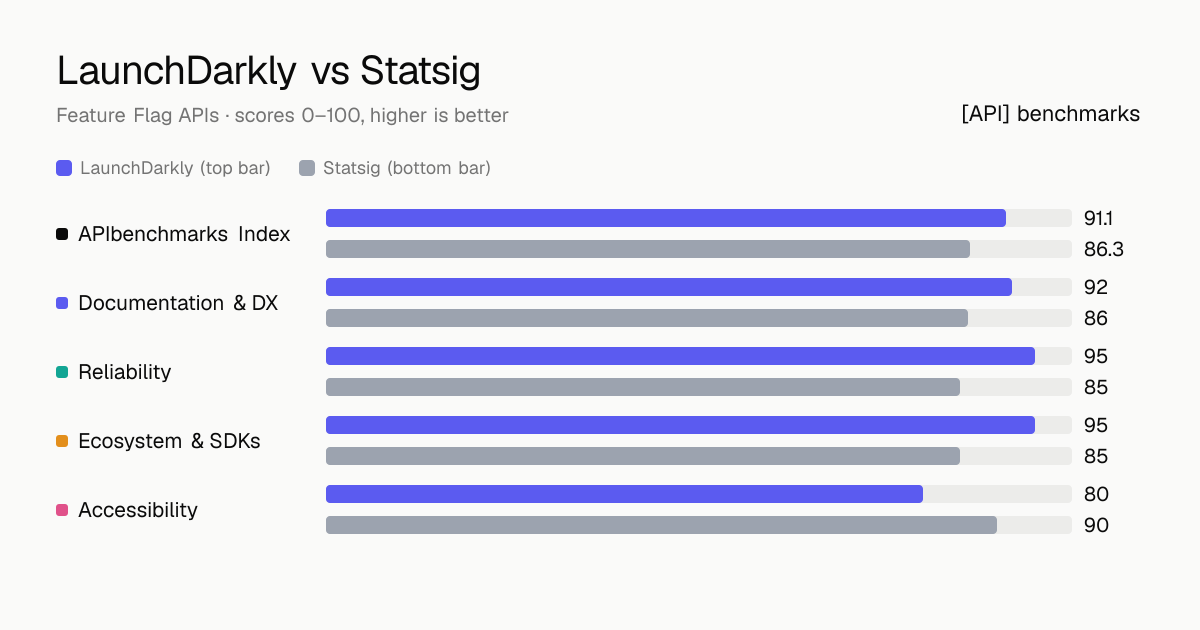
As a feature flag API, LaunchDarkly rates higher on the APIbenchmarks Index, 91.1 to 86.3, a 4.8-point gap. Here is how they compare on each criterion.
Criterion by criterion
| Criterion | LaunchDarkly | Statsig |
|---|---|---|
| Documentation & DX | ||
| Reliability | ||
| Ecosystem & SDKs | ||
| Accessibility | ||
| APIbenchmarks Index | 91.1 | 86.3 |
Specifications
| LaunchDarkly | Statsig | |
|---|---|---|
| Best for | Enterprise feature management and progressive delivery | Flags + experimentation + product analytics |
| Free tier | Developer plan: unlimited flags, 1 project, 2 environments, 1k MAU for experimentation | Free: unlimited flag checks + 2M metered events/mo, up to ~1M MTUs |
| Pricing | Per-seat + MAU-based | Per metered event / MTU-based |
| Official SDKs | 12 languages | 12 languages |
Is LaunchDarkly better than Statsig?
On the APIbenchmarks Index, LaunchDarkly rates higher (91.1 vs 86.3). It leads on the four weighted criteria, but price is reported separately, so the best choice still depends on your budget.
Verdict in one line
LaunchDarkly leads by 4.8 points (91.1 vs 86.3) and wins 3 of 4 criteria; Statsig wins 1.
Winner by criterion
| Criterion | Winner | ||
|---|---|---|---|
| Documentation & DX | 92 | 86 | |
| Reliability | 95 | 85 | |
| Ecosystem & SDKs | 95 | 85 | |
| Accessibility | 80 | 90 |
Choose LaunchDarkly if… / choose Statsig if…
- →documentation & dx matters most to you (92 vs 86)
- →reliability matters most to you (95 vs 85)
- →ecosystem & sdks matters most to you (95 vs 85)
- →your use case matches its focus: enterprise feature management and progressive delivery
- →accessibility matters most to you (90 vs 80)
- →your use case matches its focus: flags + experimentation + product analytics
Pricing side by side
- Model
- Per-seat + MAU-based
- Free tier
- Developer plan: unlimited flags, 1 project, 2 environments, 1k MAU for experimentation
- Developer$0/month
- Foundation$10 per service connection/mo (or $8.33 per 1K client-side MAU/mo)
- EnterpriseCustom
- GuardianCustom
- Model
- Per metered event / MTU-based
- Free tier
- Free: unlimited flag checks + 2M metered events/mo, up to ~1M MTUs
- Developer (Free)$0/month
- Pro$150/month
- EnterpriseCustom
Vendor-published pricing, verified 2026-06-27 (LaunchDarkly) and 2026-06-27 (Statsig).
SDK and language coverage
Both · 6
.NET (server & client)GoNode.js (server & client)PythonRubyPHP
Only LaunchDarkly · 6
JavaErlangHaskellJavaScript / React WebiOS (Swift/Objective-C)Android, Flutter, React Native, C++, Roku (mobile/client); edge SDKs for Cloudflare, Vercel, Fastly
Only Statsig · 6
JavaScript (Web)React / React NativeNext.jsAngularJava / KotlinRust
Strengths and weaknesses
- +Local in-memory SDK evaluation adds effectively zero latency (microseconds per flag check) and keeps apps serving flags during platform outages
- +Best-in-class targeting: percentage rollouts, segments, and rules on virtually any context attribute, enabling canary, ring, and progressive deployments
- +Instant kill switch lets teams revert a bad release without a redeploy, a top reason reviewers cite for production confidence
- –Expensive for small teams and startups; per-seat/per-connection costs are a frequent complaint and median enterprise contracts run ~$72k/year
- –Pricing model is complex and hard to predict, layering service connections, per-1K MAU charges, and metered add-ons for experimentation, session replay, and AI runs
- –Provisioning seats is reported as a recurring friction point due to cost
- +Feature-flag and dynamic-config checks are unlimited and free on every tier, you never pay per flag evaluation
- +No per-seat pricing: adding engineers or PMs doesn't change the bill
- +Generous free Developer tier (2M events, unlimited flag checks, 50k session replays, 1-yr retention)
- –Event-/experiment-based metered pricing can produce large surprise bills at high traffic once analytics, experiments or session replay are heavily used
- –No self-hosted / on-prem option, a blocker for strict data-sovereignty requirements
- –Proprietary statistical models are a 'black box', making it hard for data-science teams to validate p-value calculations or run custom frameworks
LaunchDarkly vs Statsig: questions
- Which has better documentation, LaunchDarkly or Statsig?
- LaunchDarkly scores higher on documentation and developer experience: 92 vs 86 out of 100.
- Which is more reliable, LaunchDarkly or Statsig?
- LaunchDarkly scores higher on reliability: 95 vs 85 out of 100.
- Do LaunchDarkly and Statsig have a free tier?
- LaunchDarkly: yes (Developer plan: unlimited flags, 1 project, 2 environments, 1k MAU for experimentation). Statsig: yes (Free: unlimited flag checks + 2M metered events/mo, up to ~1M MTUs).
- How are LaunchDarkly and Statsig priced?
- LaunchDarkly: Per-seat + MAU-based. Statsig: Per metered event / MTU-based.
- Which has more official SDKs?
- Both list 12 official SDKs.