
Head to head
Groq vs Mistral La Plateforme
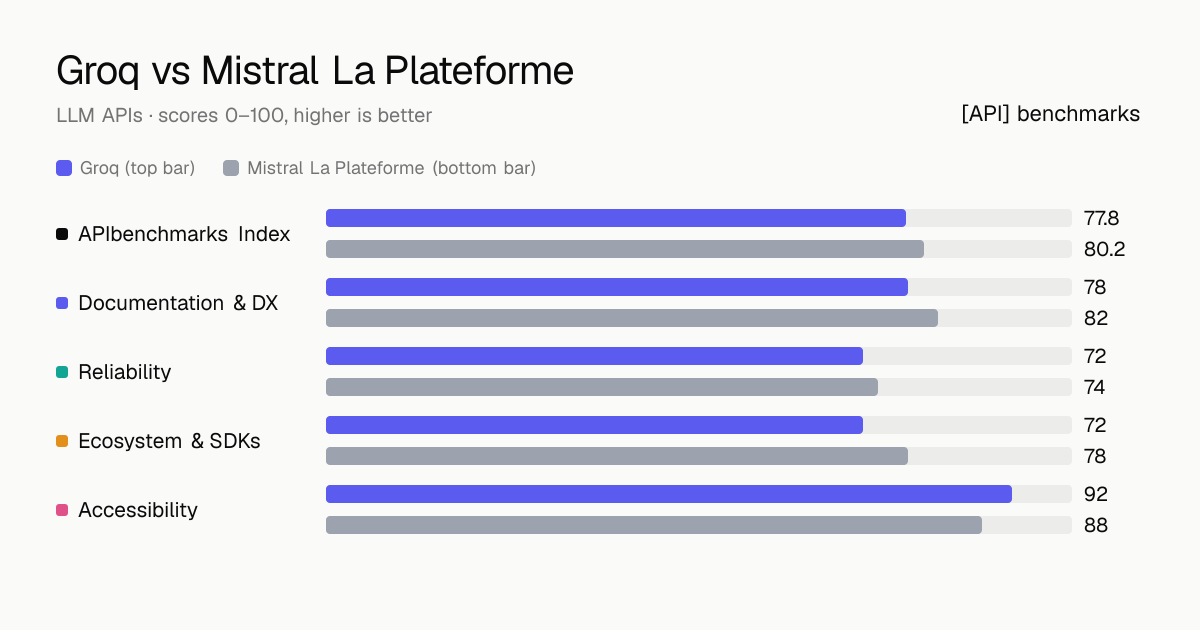
As a llm API, Mistral La Plateforme rates higher on the APIbenchmarks Index, 80.2 to 77.8, a 2.4-point gap. Here is how they compare on each criterion.
Criterion by criterion
| Criterion | Groq | Mistral La Plateforme |
|---|---|---|
| Documentation & DX | ||
| Reliability | ||
| Ecosystem & SDKs | ||
| Accessibility | ||
| APIbenchmarks Index | 77.8 | 80.2 |
Specifications
| Groq | Mistral La Plateforme | |
|---|---|---|
| Best for | Ultra-low-latency open-model inference | Open-weight European LLMs |
| Free tier | Free dev tier, no card: 30 RPM / 6K TPM / 14,400 req/day | Free Experiment tier, rate-limited (~1B tokens/mo cap), all models |
| Pricing | Per token | Per token |
| Official SDKs | 8 languages | 6 languages |
Is Groq better than Mistral La Plateforme?
On the APIbenchmarks Index, Mistral La Plateforme rates higher (80.2 vs 77.8). It leads on the four weighted criteria, but price is reported separately, so the best choice still depends on your budget.
Verdict in one line
Mistral La Plateforme leads by 2.4 points (80.2 vs 77.8) and wins 3 of 4 criteria; Groq wins 1.
Winner by criterion
| Criterion | Winner | ||
|---|---|---|---|
| Documentation & DX | 78 | 82 | |
| Reliability | 72 | 74 | |
| Ecosystem & SDKs | 72 | 78 | |
| Accessibility | 92 | 88 |
Choose Groq if… / choose Mistral La Plateforme if…
- →accessibility matters most to you (92 vs 88)
- →you need broad SDK coverage (8 official SDKs vs 6)
- →your use case matches its focus: ultra-low-latency open-model inference
- →documentation & dx matters most to you (82 vs 78)
- →reliability matters most to you (74 vs 72)
- →ecosystem & sdks matters most to you (78 vs 72)
- →your use case matches its focus: open-weight european llms
Pricing side by side
- Model
- Per token
- Free tier
- Free dev tier, no card: 30 RPM / 6K TPM / 14,400 req/day
- Free (GroqCloud)$0
- Developer / Pay-as-you-go (On-Demand)Per-token, usage-based
- Batch API50% off standard per-token pricing
- EnterpriseCustom (contact sales)
- Model
- Per token
- Free tier
- Free Experiment tier, rate-limited (~1B tokens/mo cap), all models
- Mistral Large 3 (mistral-large-latest)$0.50 / $1.50 per 1M tokens
- Mistral Medium 3.5 (mistral-medium-latest)$1.50 / $7.50 per 1M tokens
- Mistral Small 4 (mistral-small-latest)$0.15 / $0.60 per 1M tokens
- Ministral 3 - 3B (ministral-3b-latest)$0.10 / $0.10 per 1M tokens
- Codestral (codestral-latest)$0.30 / $0.90 per 1M tokens
- Free Experiment tier + Batch API$0 free tier; 50% off batch
Vendor-published pricing, verified 2026-06-27 (Groq) and 2026-06-27 (Mistral La Plateforme).
SDK and language coverage
Both · 1
Python (groq)
Only Groq · 7
TypeScript / Node.js (groq-sdk)OpenAI SDK (drop-in via base URL)LangChainVercel AI SDKLiteLLMOpenRouter (third-party routing)REST / HTTP API
Only Mistral La Plateforme · 5
TypeScript / JavaScript (@mistralai/mistralai)REST API (OpenAI-compatible)Available via Amazon BedrockAvailable via Azure AIAvailable via Google Vertex AI
Strengths and weaknesses
- +Top-ranked output speed on shared models (~322 t/s on Llama 3.3 70B per Artificial Analysis), far above typical GPU providers
- +Very low time-to-first-token (sub-1s), ideal for real-time agents and voice pipelines
- +OpenAI-compatible API, migrate with a one-line base-URL change, reuse existing OpenAI SDK code
- –Open-weight models only, no Claude, GPT-4-class, or Gemini
- –Persistent rate-limit and over-capacity (429) complaints; free tier is tight (~30 RPM)
- –Rate limits are pooled per-organization, not per-key, so adding keys does not raise capacity
- +Aggressively low pricing, Mistral Large 3 at $0.50/$1.50 per 1M tokens undercuts comparable US frontier flagships
- +Many models ship as open weights, enabling self-hosting and avoiding vendor lock-in
- +Lowest time-to-first-token among providers serving its models in Artificial Analysis benchmarks
- –First-party endpoint throughput trails cloud partners, ~49 tok/s on Large 3 vs ~215 tok/s on Amazon Bedrock
- –Reports of intermittent downtime and slow/failed requests on Trustpilot
- –Support described as slow and sometimes templated/AI-generated with inaccurate references
Groq vs Mistral La Plateforme: questions
- Which has better documentation, Groq or Mistral La Plateforme?
- Mistral La Plateforme scores higher on documentation and developer experience: 82 vs 78 out of 100.
- Which is more reliable, Groq or Mistral La Plateforme?
- Mistral La Plateforme scores higher on reliability: 74 vs 72 out of 100.
- Do Groq and Mistral La Plateforme have a free tier?
- Groq: yes (Free dev tier, no card: 30 RPM / 6K TPM / 14,400 req/day). Mistral La Plateforme: yes (Free Experiment tier, rate-limited (~1B tokens/mo cap), all models).
- How are Groq and Mistral La Plateforme priced?
- Groq: Per token. Mistral La Plateforme: Per token.
- Which has more official SDKs?
- Groq lists 8 official SDKs, Mistral La Plateforme lists 6.